 |
Jungo WinDriver
Official Documentation
|
|
Jungo WinDriver
Official Documentation
|
Once your user-mode driver has been written and debugged, you might find that certain modules in your code do not operate fast enough (for example: an interrupt handler or accessing I/O mapped regions). If this is the case, try to improve performance in one of the following ways:
In general (this is true for most cases) I/O transfers from and to your PCI device could be of the following types: (This could vary depending on the device)
| Transfer type | Speed | Hardness of implementation |
|---|---|---|
| Blocking | Slowest | Easy, use WDC_ReadAddrBlock() / WriteAddrBlock() |
| Non Blocking | Slower | Easy, use WDC_ReadAddrXXX / WDC_WriteAddrXXX |
| DMA with interrupts method | Fast | Harder to implement, requires using WDC_DMASGBufLock() / WDC_DMAContigBufLock() and a firm understanding of the device's specifics |
| DMA with polling method | Fastest | Harder to implement, requires using WDC_DMASGBufLock() / WDC_DMAContigBufLock() and a firm understanding of the device's specifics |
WinDriver's enhanced support's advantage is that it saves the developer time on getting acquainted with the popular DMA IPs available on the market today, and allows them to utilize DMA without having to spend time on learning how to implement DMA for their device, or at least reducing their learning curve. For more info see Chapter 9: Enhanced Support for Specific Chipsets.
Use the following checklist to determine how to best improve the performance of your driver.
The following checklist will help you determine how to improve the performance of your driver:
ISA Card — accessing an I/O-mapped range on the card
When transferring a large amount of data, use block (string) transfers and/or group several data transfer function calls into a single multi-transfer function call,
as explained in 11.1.3.2. Block Transfers and Grouping Multiple Transfers (Burst Transfer) below.
If this does not solve the problem, handle the I/O at kernel mode by writing a Kernel PlugIn driver, as explained in Chapter 12: Understanding the Kernel PlugIn and Chapter 13: Creating a Kernel PlugIn Driver.
PCI Card — accessing an I/O-mapped range on the card
Avoid using I/O ranges in your hardware design. Use Memory mapped ranges instead as they are accessed significantly faster.
Accessing a memory-mapped range on the card
Try to access memory directly instead of using function calls, as explained in 11.2.2. Implementing Scatter/Gather DMA below. When transferring large amounts of data, consider also the solution to problem #1 above.
If the problem persists, then there is a hardware design problem. You will not be able to increase performance by using any software design method, writing a Kernel PlugIn, or even by writing a full kernel driver.
Interrupt latency — missing interrupts, receiving interrupts too late
Handle the interrupts in the kernel mode by writing a Kernel PlugIn driver,
as explained in Chapter 12: Understanding the Kernel PlugIn and
Chapter 13: Creating a Kernel PlugIn Driver.
PCI target access vs. master access
PCI target access is usually slower than PCI master access (bus-master DMA). For large data transfers, bus-master DMA access is preferable. Read 11.2. Performing Direct Memory Access (DMA) to learn how to use WinDriver to implement bus master DMA.
There are two PCI transfer options: reading/writing to FIFO (string transfers), or reading/writing to different memory blocks.
In the case of reading/writing to memory blocks, the data is transferred to/from a memory address in the PC from/to a memory address in the card, and then both the card’s memory address and the PC’s memory address are incremented for the next transfer. This way, the data is transferred between the address in the PC and the same relative address in the card.
PCI Transfer
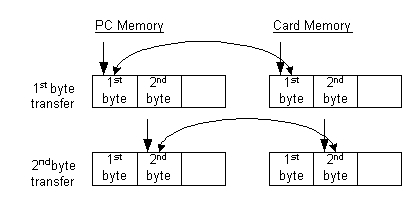
In the case of reading/writing to FIFO, the data is transferred to/from a memory address in the PC from/to a single address in the card, and then only the PC’s memory address is incremented for the next transfer. This way the data is transferred between incremented memory addresses in the PC and the same FIFO in the card’s memory.
PCI String Transfer

The WD_TRANSFER structure includes an automatic increment flag, called [fAutoinc] (WD_TRANSFER_fAutoinc). When defined as TRUE, the I/O or memory address is incremented for transfer to/from FIFO (string transfers), when defined as FALSE, all data is transferred to the same port/address.
For more information on PCI transfers, please refer to the description of WinDriver’s WD_Transfer() function, which executes a read/write instruction to an I/O port or to a memory address.
As a general rule, transfers to memory-mapped regions are faster than transfers to I/O-mapped regions, because WinDriver enables you to access memory-mapped regions directly from the user mode, without the need for a function call, as explained in 11.1.3.1. Using Direct Access to Memory-Mapped Regions.
In addition, the WinDriver APIs enable you to improve the performance of your I/O and memory data transfers by using block (string) transfers and by grouping several data transfers into a single function call, as explained in 11.1.3.2. Block Transfers and Grouping Multiple Transfers (Burst Transfer).
When registering a PCI card, using WDC_PciDeviceOpen() / WDC_IsaDeviceOpen() or the low-level WD_CardRegister() function, WinDriver returns both user-mode and kernel-mode mappings of the card's physical memory regions. These addresses can then be used to access the memory regions on the card directly, either from the user mode or from the kernel mode (respectively), thus eliminating the context switches between the user and kernel modes and the function calls overhead for accessing the memory.
The WDC_MEM_DIRECT_ADDR macro provides the relevant direct memory access base address — user-mode mapping when called from the user-mode / kernel-mode mapping when called from a Kernel PlugIn driver (see Chapter 12: Understanding the Kernel PlugIn) — for a given memory address region on the card. You can then pass the mapped base address to the WDC_ReadMem8() / WDC_ReadMem16() / WDC_ReadMem32() / WDC_ReadMem64() and WDC_WriteMem8() / WDC_WriteMem16() / WDC_WriteMem32()/ WDC_WriteMem64() macros, along with the desired offset within the selected memory region, to directly access a specific memory address on the card, either from the user mode or in the kernel. In addition, all the WDC_ReadAddr8() / WDC_ReadAddr16() / WDC_ReadAddr32() / WDC_ReadAddr64() and WDC_WriteAddr8() / WDC_WriteAddr16() / WDC_WriteAddr32() / WDC_WriteAddr64() functions — with the exception of WDC_ReadAddrBlock() and WDC_WriteAddrBlock() — access memory addresses directly, using the correct mapping, based on the calling context (user mode/kernel mode).
When using the low-level WD_xxx() APIs, the user-mode and kernel-mode mappings of the card's physical memory regions are returned by WD_CardRegister() within the pTransAddr and pUserDirectAddr fields of the pCardReg->Card.Item[i] card resource item structures. The pTransAddr result should be used as a base address in calls to WD_Transfer() or WD_MultiTransfer() or when accessing memory directly from a Kernel PlugIn driver (Chapter 12: Understanding the Kernel PlugIn).
To access the memory directly from your user-mode process, use pUserDirectAddr as a regular pointer. Whatever the method you select to access the memory on your card, it is important to align the base address according to the size of the data type, especially when issuing string transfer commands. Otherwise, the transfers are split into smaller portions.
The easiest way to align data is to use basic types when defining a buffer, i.e.:
The main methods for transferring large amounts of data between PCI-device memory addresses and a host machine’s random-access memory (RAM) are block transfers (which may or may not result in PCI burst transfers), and bus-master DMA.
Block transfers are easier to implement, but DMA is much more effective and reliable for transferring large amounts of data, as explained in 11.2. Performing Direct Memory Access (DMA).
You can use the WinDriver WDC_ReadAddrBlock() and WDC_WriteAddrBlock() functions (or the low-level WD_Transfer() function with a string command) to perform block (string) transfers — i.e., transfer blocks of data from the device memory (read) or to the device memory (write). You can use also WDC_MultiTransfer() (or the low-level WD_MultiTransfer() function) to group multiple block transfers into a single function call. This is more efficient than performing multiple single transfers. The WinDriver block-transfer functions use assembler string instructions (such as REP MOVSD, or a 64-bit MMX instruction for 64-bit transfers) to move a block of memory between PCI-mapped memory on the device and the host’s RAM. From a software perspective, this is the most that can be done to attempt to initiate PCI burst transfers.
The hardware uses PCI burst mode to perform burst transfers — i.e., transfer the data in “bursts” of block reads/writes, resulting in a small performance improvement compared to the alternative of single WORD transfers. Some host controllers implement burst transfers by grouping access to successive PCI addresses into PCI bursts.
The host-side software has no way to control whether a target PCI transfer is issued as a burst transfer. The most the host can do is initiate transfers using assembler string instructions — as done by the WinDriver block-transfer APIs — but there’s no guarantee that this will translate into burst transfers, as this is entirely up to the hardware. Most PCI host controllers support PCI burst mode for write transfers. It is generally less common to find similar burst-mode support for PCI readtransfers.
To sum it up, to transfer large amounts of data to/from memory addresses or I/O addresses (which by definition cannot be accessed directly, as opposed to memory addresses), use the following methods to improve performance by reducing the function calls overhead and context switches between the user and kernel modes:
The ability to perform actual 64-bit transfers is dependent on the existence of support for such transfers by the hardware, CPU, bridge, etc., and can be affected by any of these factors or their specific combination.
WinDriver supports 64-bit PCI data transfers on the supported 64-bit platforms, as well as on Windows and Linux 32-bit x86 platforms. If your PCI hardware (card and bus) is 64-bit, the ability to perform 64-bit data transfers on 32-bit platforms will enable you to utilize your hardware's broader bandwidth, even if your host operating system is only 32-bit.
However, note that:
This innovative technology makes possible data transfer rates previously unattainable on 32-bit platforms. Drivers developed using WinDriver will attain significantly better performance results than drivers written with the WDK or other driver development tools.
To date, such tools do not enable 64-bit data transfer on x86 platforms running 32-bit operating systems. Jungo's benchmark performance testing results for 64-bit data transfer indicate a significant improvement of data transfer rates compared to 32-bit data transfer, guaranteeing that drivers developed with WinDriver will achieve far better performance than 32-bit data transfer normally allows.
You can perform 64-bit data transfers using any of the following methods:
You can also perform 64-bit transfers to/from the PCI configuration space using WDC_PciReadCfg64() and WDC_PciReadCfgBySlot64() / WDC_PciWriteCfgBySlot64() .
The best way to improve the performance of large PCI memory data transfers is by using bus-master direct memory access (DMA), and not by performing block transfers (which as explained above, may or may not result in PCI burst transfers).
Most PCI architectures today provide DMA capability, which enables data to be transferred directly between memory-mapped addresses on the PCI device and the host’s RAM, freeing the CPU from involvement in the data transfer and thus improving the host’s performance.
DMA data-buffer sizes are limited only by the size of the host’s RAM and the available memory.
This section describes how to use WinDriver to implement bus-master Direct Memory Access (DMA) for devices capable of acting as bus masters. Such devices have a DMA controller, which the driver should program directly.
DMA is a capability provided by some computer bus architectures — including PCI and PCIe — which allows data to be sent directly from an attached device to the memory on the host, freeing the CPU from involvement with the data transfer and thus improving the host's performance.
A DMA buffer can be allocated in two ways:
The programming of a device's DMA controller is hardware specific. Normally, you need to program your device with the local address (on your device), the host address (the physical memory address on your PC) and the transfer count (the size of the memory block to transfer), and then set the register that initiates the transfer.
WinDriver provides you with API for implementing both contiguous-buffer DMA and Scatter/Gather DMA (if supported by the hardware) — see the description of WDC_DMAContigBufLock(), and WDC_DMABufUnlock() .
The following sections include code samples that demonstrate how to use WinDriver to implement Scatter/Gather DMA and contiguous-buffer DMA, and an explanation on how to preallocate contiguous DMA buffers on Windows.
The sample routines demonstrate using either an interrupt mechanism or a polling mechanism to determine DMA completion.
The sample routines allocate a DMA buffer and enable DMA interrupts (if polling is not used) and then free the buffer and disable the interrupts (if enabled) for each DMA transfer. However, when you implement your actual DMA code, you can allocate DMA buffer(s) once, at the beginning of your application, enable the DMA interrupts (if polling is not used), then perform DMA transfers repeatedly, using the same buffer(s), and disable the interrupts (if enabled) and free the buffer(s) only when your application no longer needs to perform DMA.
What is DMA Coherency?
Modern CPUs rely heavily on fast, intermediate memory caches to boost performance. When a CPU reads or writes data, it often interacts with this cache rather than the physical Random Access Memory (RAM). Direct Memory Access (DMA), however, operates independently of the CPU and accesses the physical RAM directly.
DMA coherency is the state in which both the CPU and the DMA "see" the exact same data in a shared memory buffer at any given time. If the cache and the physical RAM fall out of sync during a DMA operation, data corruption may occur.
Where and Why Do We Need It?
Cache coherency hazards typically occur in two main scenarios during DMA transfers:
When Are Synchronization Functions Required?
The need for explicit cache synchronization depends entirely on how your DMA memory buffer is allocated:
malloc()), which is cached and inherently non-coherent.DMA_ALLOW_CACHE flag to your DMA options.WinDriver Synchronization Functions
WinDriver provides two dedicated WDC API functions to handle cache coherency. They must be called at specific points during the DMA lifecycle, as demonstrated in the implementation examples in the following sections.
| Function | When to call it | What it does |
|---|---|---|
WDC_DMASyncCpu() | Before the device starts a DMA transfer. | Flushes the CPU caches to RAM (ensuring the device reads the latest CPU writes) and invalidates caches to prepare for incoming device data. |
WDC_DMASyncIo() | After the DMA transfer completes. | Ensures that any subsequent CPU reads will fetch the fresh data written to RAM by the device, bypassing any stale cache entries. |
Following is a sample routine that uses WinDriver's WDC API to allocate a Scatter/Gather DMA buffer and perform bus-master DMA transfers.
A more detailed example, which is specific to the enhanced support for PLX chipsets can be found in the
WinDriver/samples/c/plx/lib/plx_lib.c library file and
WinDriver/samples/c/plx/diag_lib/plx_diag_lib.c diagnostics library file (which utilizes the plx_lib.c DMA API).
A more detailed example, which is specific to the enhanced support for PLX chipsets can be found in the WinDriver/samples/c/plx/dotnet/lib/ library and WinDriver/samples/c/plx/dotnet/diag/ diagnostics library.
Notice the difference between ref WD_DMA wdDma and IntPtr pWdDma. The former is used by C# user functions, while the latter is used by WDC API C functions, that can only take a pointer, not a reference.
In the code sample above, it is up to you to implement the following MyDMAxxx() routines, according to your device's specification:
When using the basic WD_xxx API to allocate a Scatter/Gather DMA buffer that is larger than 1MB, you need to set the [DMA_LARGE_BUFFER] (DMA_LARGE_BUFFER) flag in the call to WD_DMALock() and allocate memory for the additional memory pages.
However, when using WDC_DMASGBufLock() to allocate the DMA buffer, you do not need any special implementation for allocating large buffers, since the function handles this for you.
Following is a sample routine that uses WinDriver's WDC API to allocate a contiguous DMA buffer and perform bus-master DMA transfers.
For more detailed, hardware-specific, contiguous DMA examples, refer to the following enhanced-support chipset sample library files:
⚠ Attention
On Linux kernels 6.2 and higher (and kernel 5.14 on Enterprise Linux such as RHEL, CentOS)
allocation of contiguous buffers requires preallocation of memory using CMA. For more info, see 11.2.3.5. Preallocating Contiguous DMA Buffers on Linux.
WinDriver/samples/c/plx/lib/plx_lib.c and WinDriver/samples/c/plx/diag_lib/plx_diag_lib.c plx_lib.c DMA API)WinDriver/samples/c/xilinx/bmd_design/bmd_lib.cIn the code sample above, it is up to you to implement the following MyDMAxxx() routines, according to your device's specification:
WinDriver doesn't limit the size of the DMA buffer that can be allocated using its DMA APIs. However, the success of the DMA allocation is dependent on the amount of available system resources at the time of the allocation. Therefore, the earlier you try to allocate the buffer, the better your chances of succeeding.
WinDriver for Windows allows you to configure your device INF file to preallocate contiguous DMA buffers at boot time, thus increasing the odds that the allocation(s) will succeed. You may preallocate a maximum of 512 buffers: — 256 host-to-device buffers and/or 256 device-to-host buffers.
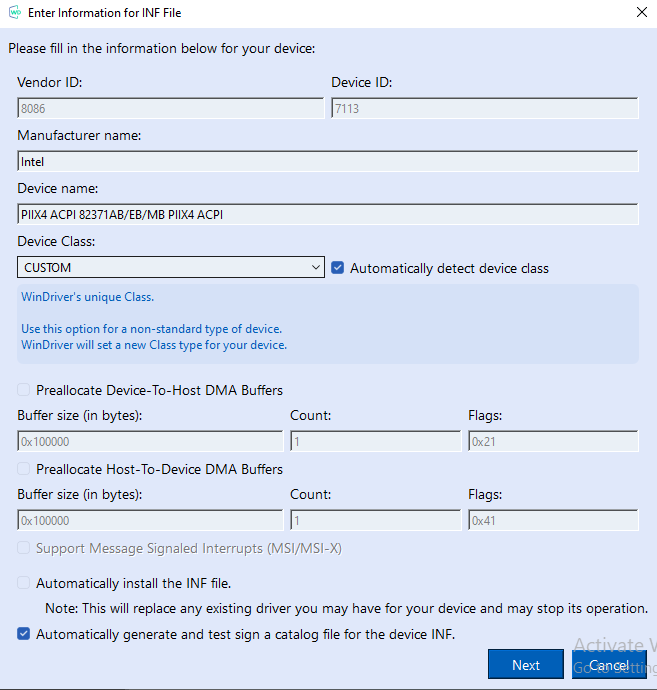
There are 2 ways to preallocate contiguous DMA buffers on Windows: directly from the DriverWizard, or manually via editing the INF file.
Directly from DriverWizard:
⚠ Attention
The Size and Flags fields must be hexadecimal numbers, formatted with the "0x" prefix, as shown below.
DriverWizard INF File Information
Manually by editing an existing INF file:
UpdateRegistryDevice registry key in your device INF file, as shown below.The examples are for configuring preallocation of eight DMA buffers but you may, of-course, select to preallocate just one buffer (or none at all). To preallocate unidirectional buffers, add these lines:
The supported WinDriver DMA flags for the dwOptions field of the WD_DMA struct are documented in [WD_DMA_OPTIONS] (WD_DMA_OPTIONS).
DmaFromDeviceCount and DmaFromDeviceCount values are supported from version 12.4.0. If those values aren’t set value of 1 will be assumed.
The Wizard-generated and relevant sample WinDriver device INF files already contain the unidirectional buffers configuration lines, so you only need to remove the comment indicator ; at the start of each line. The examples are for configuring preallocation of 8 DMA buffers (4 for each direction), but you may, of-course, select to preallocate just one buffer (or none at all, by leaving the above code commented out).
In your code, the first n calls (if you configured the INF file to preallocate n DMA buffers) to the contiguous-DMA-lock function — WDC_DMAContigBufLock() — should set parameter values that match the buffer configurations in the INF file:
⚠ Attention
For a device-to-host buffer, the DMA-options mask parameter (
dwOptions/pDma->dwOptions) should contain the same DMA flags set in theDmaFromDeviceOptionsregistry key value, and the buffer-size parameter (dwDMABufSize/pDma->dwBytes) should be set to the value of theDmaFromDeviceBytesregistry key value. For a host-to-device buffer, the DMA-options mask parameter (dwOptions/pDma->dwOptions) should contain the same flags set in theDmaToDeviceOptionsregistry key value, and the buffer-size parameter (dwDMABufSize/pDma->dwBytes) should be set to the value of theDmaToDeviceBytesregistry key value.
In calls to WDC_DMAContigBufLock(), the DMA configuration information is provided via dedicated function parameters — dwDMABufSize and dwOptions. In calls to WD_DMALock(), the information is provided within the fields of the WD_DMA struct pointed to by the pDma parameter — pDma->dwBytes and pDma->dwOptions.
When using WDC_DMAContigBufLock() you don't need to explicitly set the [DMA_KERNEL_BUFFER_ALLOC] (DMA_KERNEL_BUFFER_ALLOC) flag (which must be set in the INF-file configuration) because the function sets this flag automatically.
When using the low-level WinDriver WD_DMALock() function, the DMA options are set in the function's pDma->dwOptions parameter — which must also include the [DMA_KERNEL_BUFFER_ALLOC] (DMA_KERNEL_BUFFER_ALLOC) flag — and the buffer size is set in the pDma->dwBytes parameter.
If the buffer preallocation fails due to insufficient resources, you may need to increase the size of the non-paged pool (from which the memory is allocated).
On Linux kernels 6.2 and higher (and kernel 5.14 on Enterprise Linux such as RHEL, CentOS) allocation of contiguous buffers requires preallocation of memory using CMA. WinDriver will automatically fail contiguous DMA buffer locking on these kernels unless the DMA_OVERRIDE_CMA_VALIDATION option is added to the dwOptions parameter of WDC_DMAContigBufLock(). Be careful using this override option as it most probably will hang or crash your system.
Enable CONFIG_CMA
In order to preallocate CMA buffers you first need to make sure that the kernel is compiled with CONFIG_CMA enabled. Check it with:
Note that on different Linux distributions the config file for the running kernel may reside in different locations that the one specified above. Check your distribution's documentation to find the right path to search in. If the result will indicate that CONFIG_CMA=y then you may proceed to the next step. Otherwise, either recompile your kernel from source and enable CONFIG_CMA from the menuconfig, or download a precompiled kernel version which has it enabled. A good option is to use liqurix kernels (of versions currently supported by WinDriver), which by default are precompiled with CONFIG_CMA enabled. After replacing / recompiling the kernel - retry this step until CONFIG_CMA will appear as enabled on your running kernel.
Preallocate CMA memory using the kernel boot parameters.
As root, edit /etc/default/grub and in it edit the line with GRUB_CMDLINE_LINUX_DEFAULT to include "`cma=100M`" (to preallocate 100MB, change this parameter according to your needs).
Apply the changes to the GRUB:
On Debian/Ubuntu:
Run
On RHEL/CentOS:
on Legecy boot systems run:
on UEFI boot systems run: (replace YOUR_DISTRO_NAME with centos, redhat, etc...)
Restart the computer and verify the changes
After reboot, run
If the output indicates Cma memory exists, you may now use WDC_DMAContigBufLock() in your code and it should work.
This section describes how to use WinDriver to implement bus-master Direct Memory Access (DMA) transactions for devices capable of acting as bus masters. Such devices have a DMA controller, which the driver should program directly.
DMA is a capability provided by some computer bus architectures — including PCI and PCIe — which allows data to be sent directly from an attached device to the memory on the host, freeing the CPU from involvement with the data transfer and thus improving the host's performance.
To understand the use of WinDriver's DMA transaction API, you must be familiar with the following concepts:
DMA transaction
A DMA transaction is a complete I/O operation, such as a single read or write request from an application.
DMA transfer
A DMA transfer is a single hardware operation that transfers data from computer memory to a device or from the device to computer memory.
A single DMA transaction always consists of at least one DMA transfer, but a transaction can consist of many transfers.
A DMA transaction buffer can be allocated in two ways:
The programming of a device's DMA controller is hardware specific. Normally, you need to program your device with the local address (on your device), the host address (the physical memory address on your PC) and the transfer count (the size of the memory block to transfer), and then set the register that initiates the transfer. WinDriver provides you with an API for implementing both Contiguous-Buffer DMA transactions and Scatter/Gather DMA transactions (if supported by the hardware) — see the description of WDC_DMATransactionContigInit(), WDC_DMATransactionSGInit(), WDC_DMATransferCompletedAndCheck(), WDC_DMATransactionRelease() and WDC_DMATransactionUninit().
DMA transaction diagram
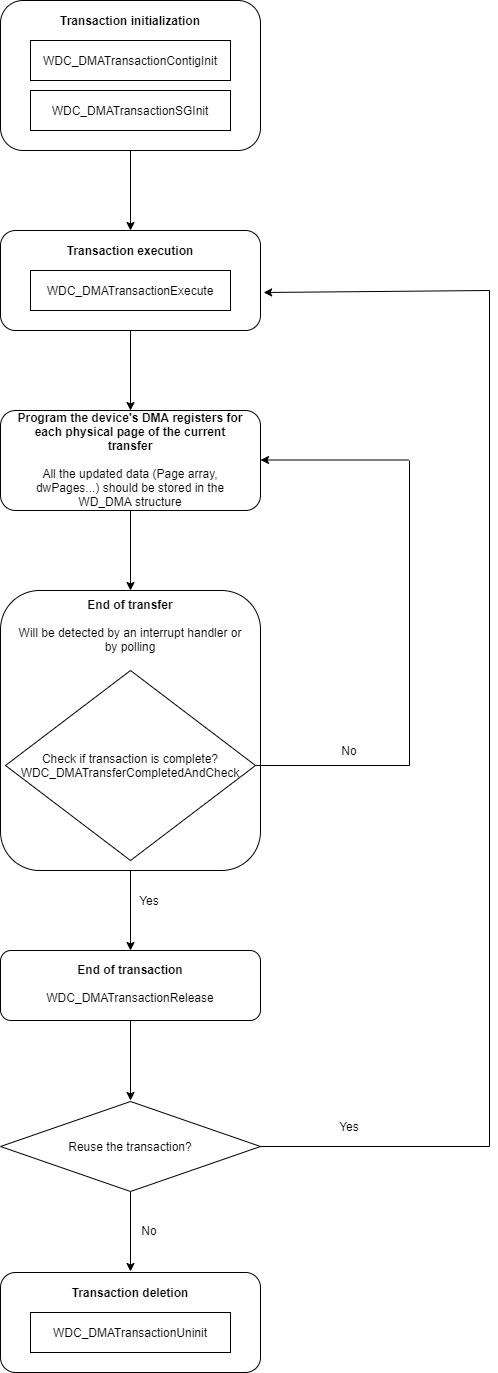
The following sections include code samples that demonstrate how to use WinDriver to implement a Scatter/Gather DMA transaction (see 11.2.2. Implementing Scatter/Gather DMA) and a Contiguous-Buffer DMA transaction (see 11.2.3. Implementing Contiguous-Buffer DMA).
The sample routines demonstrate using either an interrupt mechanism or a polling mechanism to determine DMA completion.
Following is a sample routine that uses WinDriver's WDC API to initialize a Scatter/Gather DMA transaction buffer and perform bus-master DMA transfers.
For more detailed, hardware-specific, Scatter Gather DMA transaction examples, refer to the following enhanced-support chipset (Chapter 9: Enhanced Support for Specific Chipsets) sample library files:
WinDriver/samples/c/plx/lib/plx_lib.c, WinDriver/samples/c/plx/diag_lib/plx_diag_lib.c (which utilizes the plx_lib.c DMA API) and WinDriver/samples/c/plx/9656/p9656_diag.cWinDriver/samples/c/xilinx/xdma/xdma_lib.cA detailed example, which is specific to the enhanced support for PLX chipsets can be found in the WinDriver/samples/c/plx/dotnet/lib/ library and WinDriver/samples/c/plx/dotnet/diag/ diagnostics library.
In the code sample above, it is up to you to implement the following MyDMAxxx() routines and MY_DMA_TRANSFER_ELEMENT structure according to your device's specification and your needs:
Following is a sample routine that uses WinDriver's WDC API to initialize a Contiguous- Buffer DMA transaction and perform bus-master DMA transfers.
For more detailed, hardware-specific, contiguous DMA examples, refer to the following enhanced-support chipset sample library files:
WinDriver/samples/c/plx/lib/plx_lib.c and WinDriver/samples/c/plx/diag_lib/plx_diag_lib.c (which utilizes the plx_lib.c DMA API)WinDriver/samples/c/xilinx/xdma/xdma_lib.cA detailed example, which is specific to the enhanced support for PLX chipsets can be found in the WinDriver/samples/c/plx/dotnet/lib/ library and WinDriver/samples/c/plx/dotnet/diag/ diagnostics library.
In the code sample above, it is up to you to implement the following MyDMAxxx() routines and MY_DMA_TRANSFER_ELEMENT structure according to your device's specification and your needs:
GPUDirect for RDMA is a feature available on selected NVIDIA GPUs that allows performing Direct Memory Access (DMA) between GPUs and PCI Express devices. Check out NVIDIA’s website to make sure your GPU does support GPUDirect for this purpose.
NVIDIA GPUDirect RDMA is currently supported only on Linux. We strive to add support for further GPUs and OSes in the future, please contact WinDr.nosp@m.iver.nosp@m.@jung.nosp@m.o.co.nosp@m.m for further inquiries and suggestions.
The following system requirements:
The following software prerequisities:
Unpack WinDriver from the tar file.
Make sure your WinDriver kernel module is linked with NVIDIA’s kernel module to allow GPUDIRECT.
We strongly recommend making sure you have already implemented and tested a “regular” DMA routine between your device and the computer RAM before moving on to implementing a GPUDirect DMA routine.
See previous sections for more info (11.2. Performing Direct Memory Access (DMA) or
11.3. Performing Direct Memory Access (DMA) transactions).
Assuming you have already implemented a DMA routine in your WinDriver-based code, perform the following steps to perform DMA to the GPU memory instead of the main memory.
If compiling using Make/CMake, follow this instructions and see a detailed example below:
nvcc) instead of gcc.nvcc) instead of ld.-lcuda to your linker flags(LFLAGS) in order to link with the CUDA shared libraries.-fno-pie and -m$(USER_BITS) from your linker flags.Add to your code.
Instead of using regular malloc() to allocate the memory for the pBuf parameter in the function WDC_DMASGBufLock(), use cudaMalloc().
Make sure that the dwOptions parameter of WDC_DMASGBufLock() contains the [DMA_GPUDIRECT] (DMA_GPUDIRECT) flag.
Add the following code to enable synchronous memory operations with your DMA buffer (pDma->pBuf in this example)
Use CUDA functions to access the GPU memory such as: cudaMemcpy(), cudaFree() etc. Using regular memory management functions on pointers to GPU memory might lead to crashes.
⚠ Attention
Calling
WDC_DMASGBufLock()with [DMA_GPUDIRECT] (DMA_GPUDIRECT) flag with a buffer allocated with regular memory buffer (not allocated usingcudaMalloc()) will result in an Internal System Error (Status 0x20000007).
If using CMake to compile your code – use the following recipe as a guide.
Standard DMA transfers data between a PCIe device and the host machine's RAM. When two separate PCIe devices need to share data Standard architectures require the data to be copied twice: first from Device A to host RAM, and then from host RAM to Device B.
Peer-to-Peer DMA (P2PDMA) eliminates this bottleneck. By routing traffic directly through the PCIe switch or the CPU Root Complex, P2PDMA allows one PCIe device's DMA engine to read from or write directly to the Base Address Register (BAR) memory of another PCIe device.
Key Advantages:
If you are transferring data between two custom PCIe cards (like two FPGAs), you will use standard native P2PDMA. If the target is an NVIDIA GPU, you would utilize the GPUDirect API.
Native P2PDMA is supported exclusively in Linux environments.
CONFIG_PCI_P2PDMA option enabled. While most modern, mainstream Linux distributions enable this by default, custom or embedded kernels will need this flag explicitly set during configuration.The path the data takes across the motherboard is critical:
The Linux kernel manages P2P memory resources using large memory pages, which imposes the following strict requirements:
Implementing P2PDMA involves two devices: the Initiator (your device with the DMA engine) and the Provider (the peer device exposing its BAR memory to the bus). In WinDriver, this means opening handles to both devices and locking the buffer against the Provider's memory space.
Before setting up the DMA engine, you must locate the Provider device on the PCI bus, verify it has a suitable memory BAR, and enable it for P2P access.
WD_PCI_CARD_INFO for the target provider device.WD_ITEM_MEM_P2P_ENABLE macro. You must provide the desired size and an offset, which must be aligned to a 2MB boundary.WDC_PciDeviceOpen() to open a handle to the provider device.In a standard DMA transfer, you lock a user-mode buffer in host RAM. For P2PDMA, you lock a buffer directly against the Provider device's handle.
Pass the Provider device's handle to WDC_DMASGBufLock() (via the WDC_GET_CARD_HANDLE macro) and include the DMA_P2PDMA flag in your options.
After the P2P DMA buffer is locked, use the physical pages returned in the WD_DMA structure to program the DMA engine on the Initiator device. Unlike regular Scatter/Gather DMA, P2PDMA does not use a user-mode memory buffer: the locked memory belongs to the Provider device's BAR. Therefore, do not allocate, copy to, dereference, or free a user buffer for this transfer, and do not call WDC_DMASyncCpu() or WDC_DMASyncIo() for the P2P buffer.
The following example shows the typical flow. The MyDMAxxx() routines are device-specific, as in the standard DMA example in 11.2.2.3. What Should You Implement?.
In this flow, the Provider device supplies the memory and the Initiator device performs the DMA. The Initiator's DMA engine must be programmed with the bus addresses and lengths from pDma->Page[], just as it would be programmed with host-memory pages in a regular Scatter/Gather DMA transfer. The direction flag is from the Initiator's point of view: use DMA_TO_DEVICE when the Initiator writes to the Provider memory, and DMA_FROM_DEVICE when the Initiator reads from the Provider memory. Use DMA_TO_FROM_DEVICE only when the same locked P2P buffer is used for both directions.
Warning: Direct CPU reads or writes to the P2P DMA buffer (for example, attempting to use memcpy() to read the data buffer) are not supported. Because the memory physically resides on the peer device and is not standard host RAM, direct user-space access is invalid. If you need to retrieve and verify the buffer's contents, you must initiate a standard, non-P2P DMA transfer back to host memory.
WinDriver includes built-in diagnostic sample applications that demonstrate and test P2PDMA capabilities out of the box:
How to Run P2PDMA Diagnostic Tests:
mcdma_diag or xdma_diag utility on your Linux target machine.WinDriver supports the implementation of interrupt service routines and locking down DMA buffers into memory, giving you the physical addresses and lengths of the kernel DMA buffer.
Assuming you want to implement slave DMA for an ISA card, you will need to write the code to program the DMA controller yourself. There is no specific API to program the system DMAC on PCs, but you can use the generic WinDriver API for direct hardware access and DMA allocation from your application
(see specifically WDC_DMAContigBufLock(), WDC_DMASGBufLock(),
and the WDC_PciReadCfg8() / WDC_PciReadCfg16() / WDC_PciReadCfg32() / WDC_PciReadCfg64()
and WDC_PciWriteCfg8() / WDC_PciWriteCfg16() / WDC_PciWriteCfg32() / WDC_PciWriteCfg64() or the lower-level WD_DMALock() and WD_Transfer() APIs).
“Regular” memory (stack, heap, etc.) is cached by the operating system. When using WinDriver DMA APIs, the data is non-cached, in order to make it DMA-safe. Therefore, the memory access is slower. Note that this is the correct behavior for DMA.
When performing Contiguous Buffer DMA, you can set the DMA_ALLOW_CACHE flag in the dwOptions parameter of WDC_DMAContigBufLock(), or directly in the dwOptions field of the WD_DMA structure that is passed to WD_DMALock() (when using the low-level WinDriver API), in order to allocate a cached DMA buffer. When working on Windows x86 and x86_64 platforms, it is recommended to always set this flag.
If you have allocated the memory in the user mode and then passed its address to WDC_DMASGBufLock() or to the low-level WD_DMALock() function in order to lock a Scatter/Gather DMA buffer, then calling WD_DMAUnlock() will unlock the memory buffer and it will now function like other “regular” memory in terms of access speed.
WinDriver does not impose any inherent limitation on the size of the DMA buffer that can be allocated using its DMA APIs. However, the success of the DMA allocation is dependent of the amount of available system resources at the time of the attempted allocation. Therefore, the earlier your try to allocate the buffer, the better your chances of succeeding.
For contiguous-buffer DMA allocation, there must be enough contiguous physical memory for the allocation. On Windows, WinDriver allows preallocation of DMA buffers to evade this, so please refer to the relevant chapter of the manaul for more information.
When allocating a Scatter/Gather DMA buffer that is larger than 1MB, using the low-level WinDriver API, be sure to set the [DMA_LARGE_BUFFER] (DMA_LARGE_BUFFER) flag in the dwOptions field of the WD_DMA() structure that is passed to WD_DMALock(). (When using the high-level WDC_DMASGBufLock() function, this flag is already handled internally by the function.)
The DMA buffer allocated by WinDriver uses page-locked memory, to ensure a safe DMA operation. This memory is allocated from Windows' non-paged kernel pool of memory. The size of this pool is fixed at boot time by a Registry setting. You can increase the allocated memory by increasing the value of the NonPagedPoolSize Registry entry, found under HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Control\Session Manager\Memory Management.
Sometimes, there is enough contiguous memory, but there are not enough page table entries to map the memory. Even after increasing the value of the relevant Registry entries, the memory allocation might still fail, specifically when trying to allocate a very large buffer (such as 1GB). The solution in this case is to try decreasing the size of the buffer you are trying to lock, until you succeed.
⚠ Attention
Please note that the WinDriver DMA allocation APIs ((WDC_DMAContigBufLock() / WDC_DMASGBufLock() / WD_DMALock()) also map the physical memory of the allocated buffer into virtual user mode space. Therefore, there must also be enough free virtual memory to enable the mapping of the entire buffer into the user space.
See 11.2. Performing Direct Memory Access (DMA) and 11.3. Performing Direct Memory Access (DMA) transactions.
Locate and register both cards (using WDC_PciScanDevices(), WDC_PciGetDeviceInfo() and
WDC_PciScanDevices()). At least one of the cards must be PCI DMA Master Capable.
Program it with the physical address of the Slave card. Obtaining this address is possible by using pciCard.Card.Item[i].I.Mem.pPhysicalAddr, set by WDC_PciGetDeviceInfo() for the slave card.
Refer to the DMA section of this manual for more info regarding programming DMA using WinDriver.
 1.9.7